Document management
Enterprise Document Repository & Extraction Engine
High-volume ingestion, classification and search across business documents, with permissions, retention and a complete audit trail.
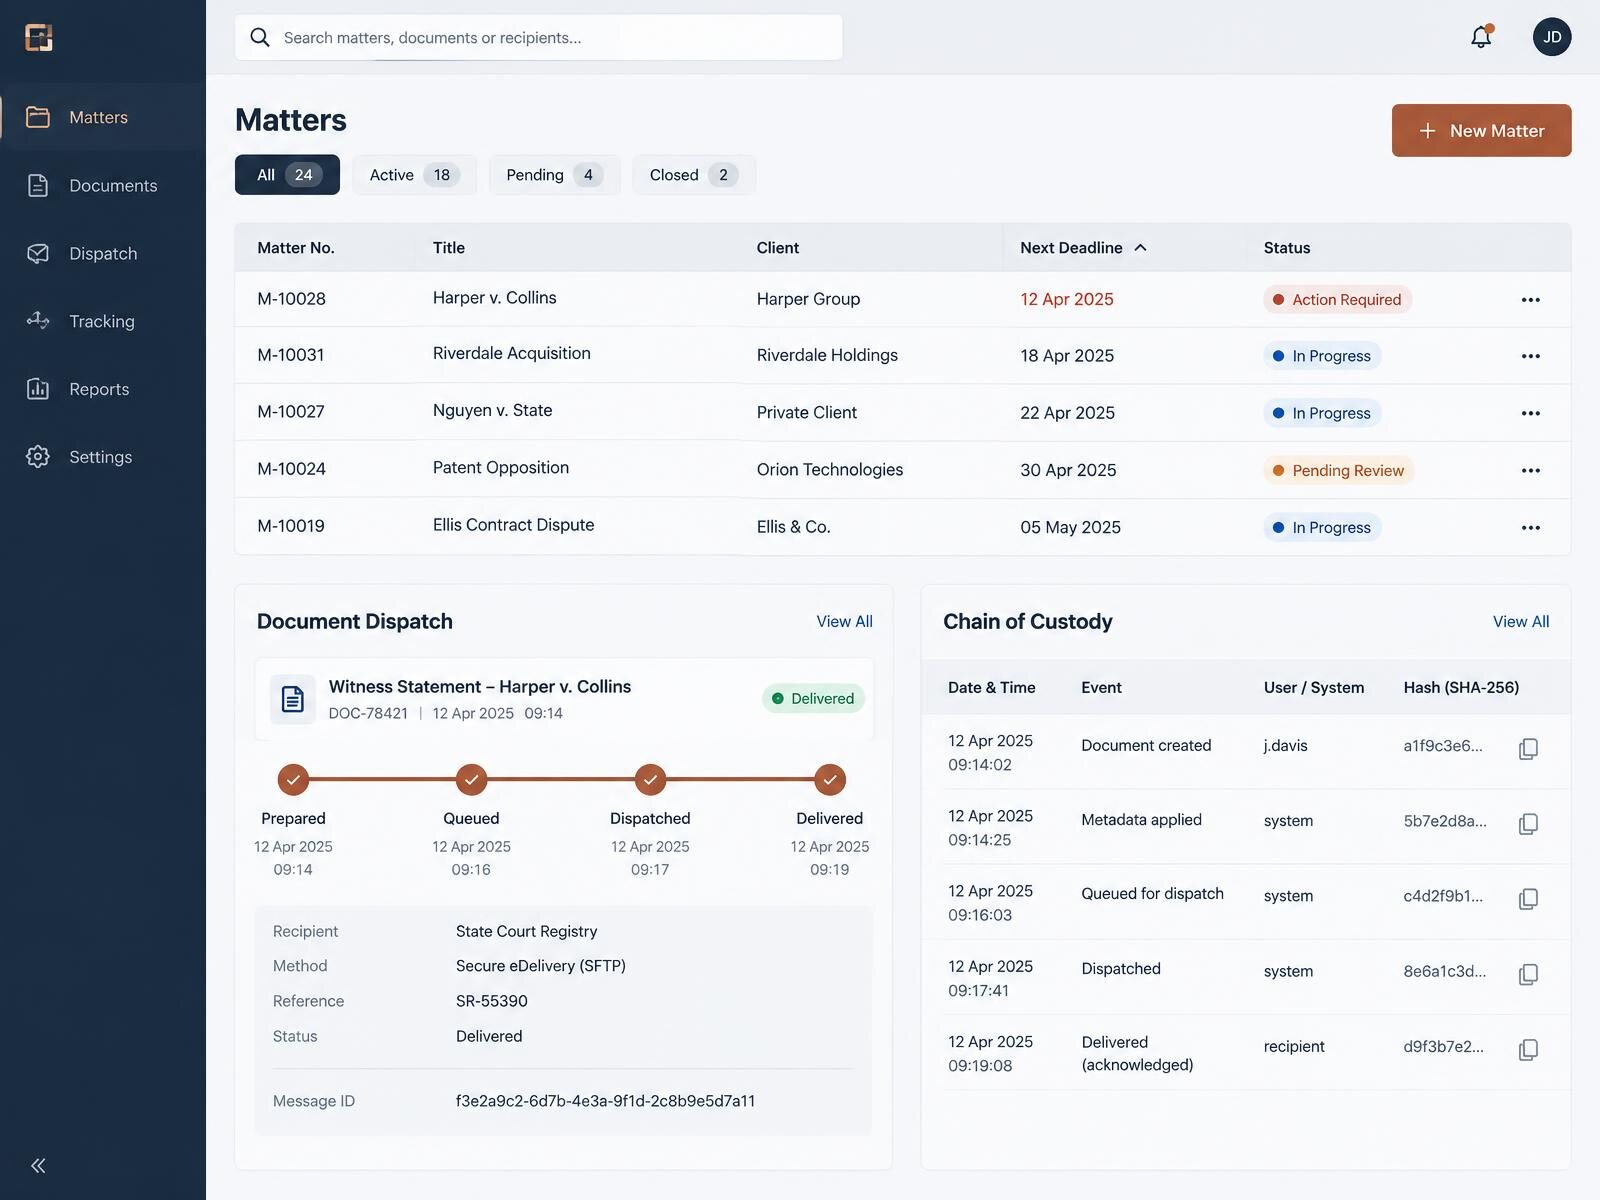
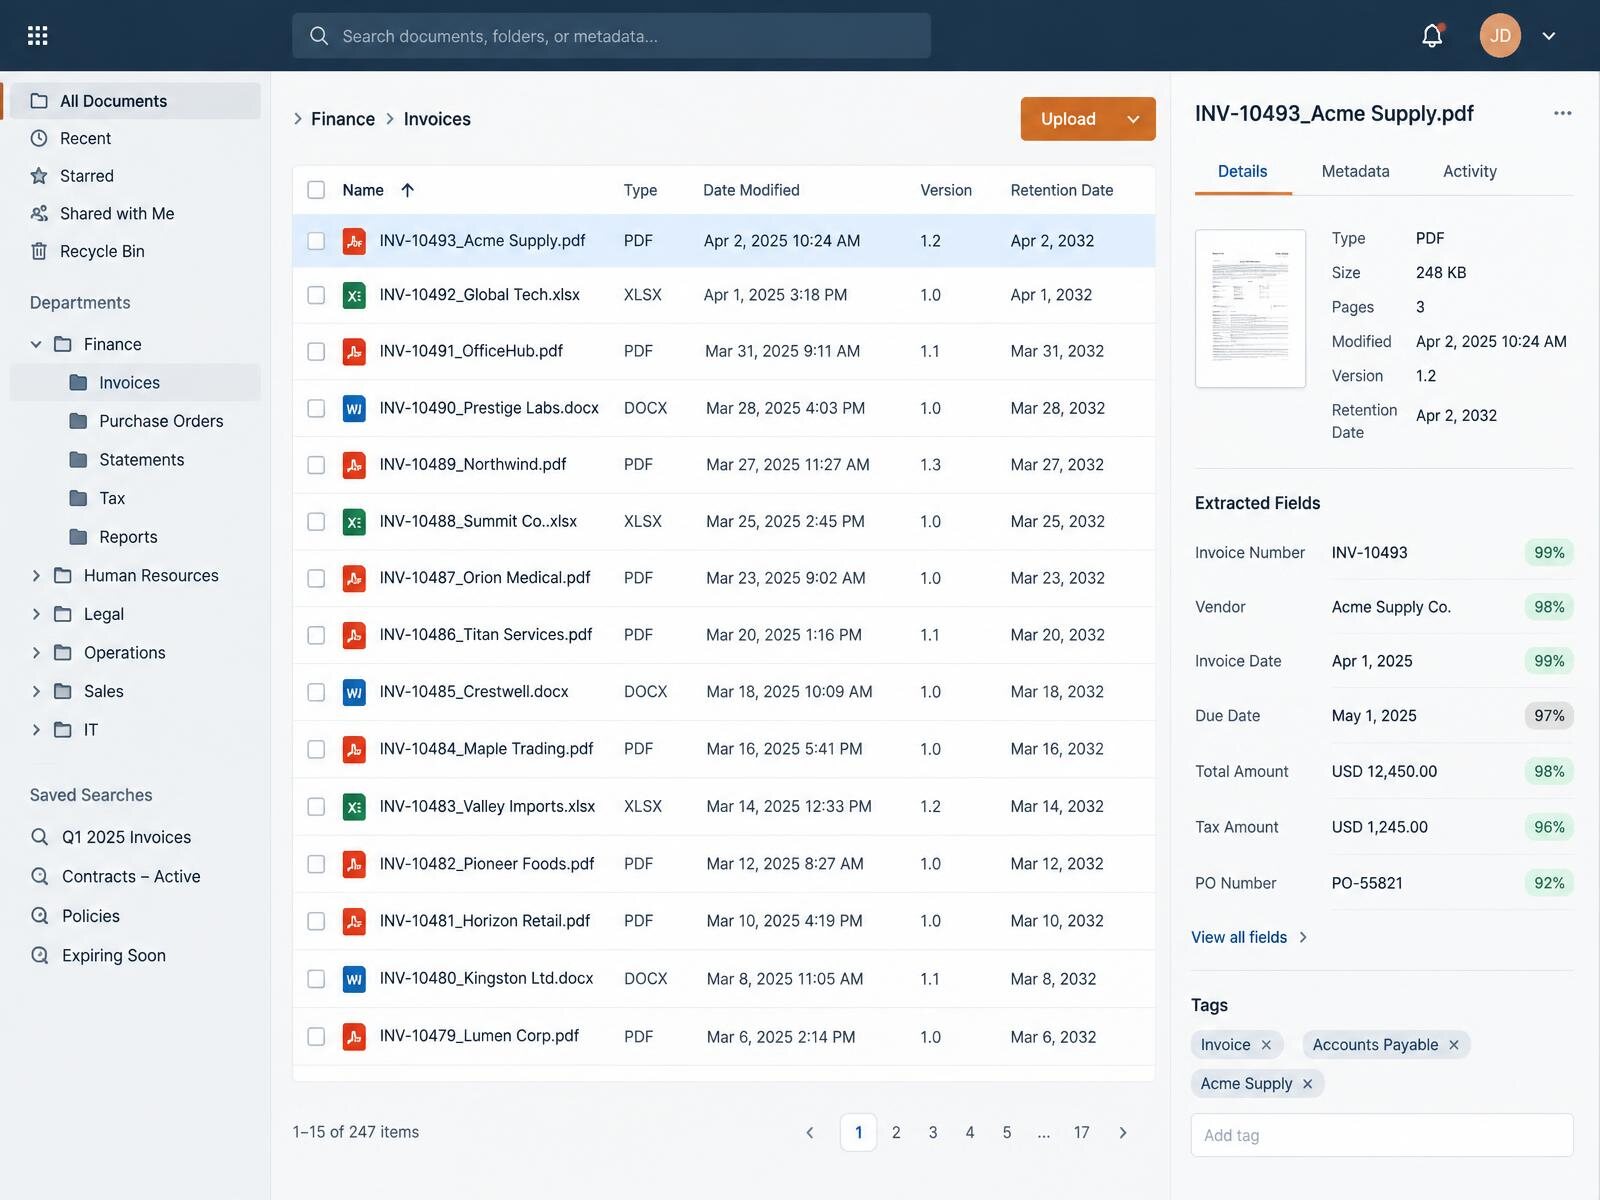
The reference architecture behind the domain we know best. Documents arrive from multiple sources, are classified and indexed, have their key fields extracted and validated, and are held under explicit permission and retention rules. Low-confidence extractions are routed for review rather than accepted silently, and every action against a record is logged.
- Multi-source ingestion with automatic classification
- OCR, key-field extraction and confidence thresholds
- Role-based permissions, versioning and retention policy
- Full-text search and tamper-evident audit logging
Related service Almas reference architecture — demonstration interface